Chuyên gia khoa học dữ liệu · Phân tích thể thao · Valencia

Tôi chuyển đổi dữ liệu thành các quyết định rõ ràng

Tôi là cầu nối giữa phân tích dữ liệu và thể thao đỉnh cao: tôi chuyển hóa các chỉ số hiệu suất thành chiến lược tạo nên sự khác biệt trên sân thi đấu.

  • Python
  • R
  • SQL
  • Power BI
  • Machine Learning
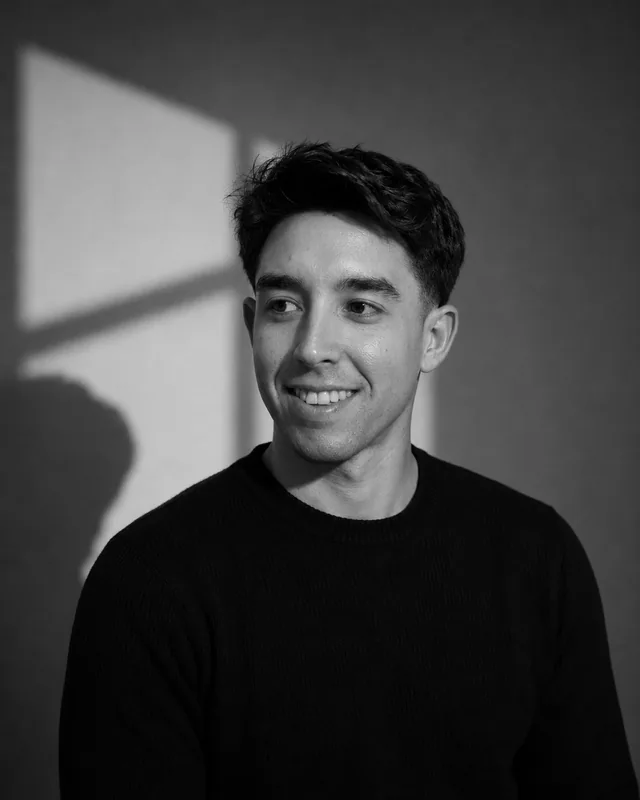
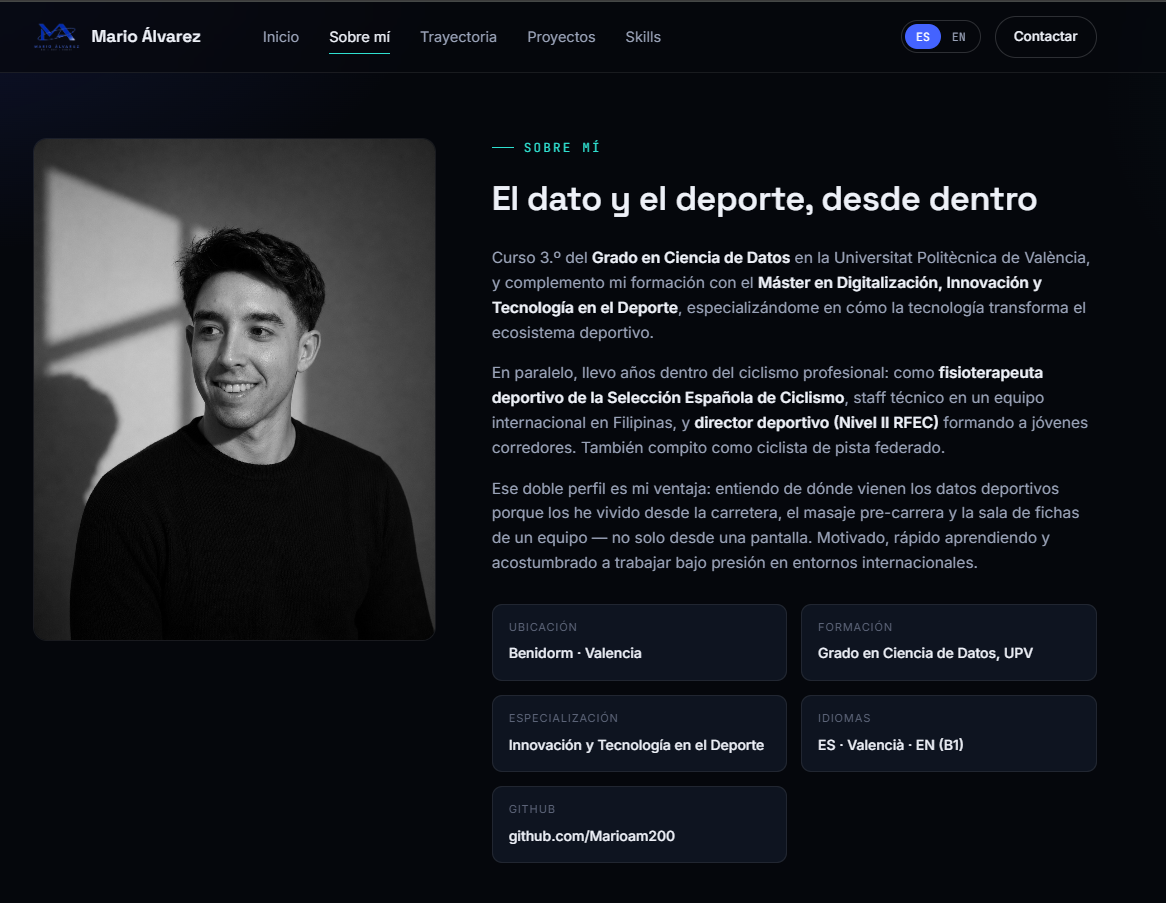
Retrato de Mario Álvarez

Về tôi

Dữ liệu với bối cảnh thi đấu trên đường đua và trong các giải đấu

Tôi là Mario Álvarez, sinh viên ngành Khoa học Dữ liệu tại UPV với kinh nghiệm thực tế trong bộ môn đua xe đạp chuyên nghiệp. Tôi kết hợp phân tích dữ liệu với hiệu suất thể thao đỉnh cao, để biến mỗi chỉ số thành một quyết định cải thiện kết quả.

Xem thêm

UPV

Học vấn

Cử nhân Khoa học Dữ liệu, Đại học Bách khoa Valencia.

Tinh hoa

Kinh nghiệm

Làm việc thực tế trong một đội đua xe đạp chuyên nghiệp.

Data + Sport

Phương pháp tiếp cận

Phân tích được áp dụng để nâng cao hiệu suất thể thao.

Kinh nghiệm

Hai thế giới, một ngôn ngữ chung: hiệu suất

Tôi đã thi đấu ở cấp độ cao nhất và ngày nay tôi áp dụng tiêu chí đó vào dữ liệu: tôi hiểu một con số có ý nghĩa gì đối với một vận động viên vì tôi chính là vận động viên đó.

Xem thêm

Công việc

Dự án

Tuyển chọn tự động các kho lưu trữ công khai của tôi trên GitHub.

Chuyên môn

  • HTML
  • Power BI
  • Python
  • R
  • SQL

VIS

HTML

This repository contains coursework, practical exercises, and study materials for a university data visualization course. It includes solved programming tasks using R and Python libraries like ggplot2 and Plotly, alongside practice dashboards built in Tableau.

Xem trên GitHub
EVALUACION-DE-MODELOS-

HTML

This repository contains practical assignments for a university model evaluation course, covering topics such as cost-sensitive classification, fairness metrics on the COMPAS dataset, and model interpretability using partial dependence plots. The exercises and analyses are implemented using Python and R across Jupyter Notebooks and R Markdown reports.

Xem trên GitHub

TRABAJO_MDP

An academic data analysis project in R that explores and characterizes a physicochemical crystal dataset. It covers data cleaning, preprocessing, and dimensionality reduction through Principal Component Analysis (PCA) using packages such as FactoMineR, factoextra, and ggplot2.

Xem trên GitHub

TRABAJO_CORREDORES

Python

A Streamlit web application that helps manage cycling teams by scraping race and rider data from ProCyclingStats and FirstCycling to analyze upcoming events and cyclist specialties. It is built with Python using BeautifulSoup, Selenium, Pandas, and the Gemini API to process data and extract UCI points regulations from PDFs.

Xem trên GitHub

COFIDIS

Python

Developed as an academic project, this tool scrapes UCI rankings and race data from ProCyclingStats to calculate race difficulty scores tailored to the Cofidis cycling team's calendar. It is built with Python, using Selenium and BeautifulSoup for web scraping, Pandas for data processing, and Streamlit for the interactive interface.

Xem trên GitHub
Xem tất cả các dự án

Chúng ta nói về dữ liệu chứ?

Hãy kể cho tôi nghe về dự án của bạn và chúng ta sẽ cùng nhau tìm ra những quyết định giúp cải thiện hiệu suất.

Đi tới liên hệ