ڈیٹا سائنٹست · کھیلوں کے تجزیات · والنسیا

میں ڈیٹا کو تبدیل کرتا ہوں واضح فیصلوں میں

میں ڈیٹا کے تجزیے اور ایلیٹ کھیلوں کے درمیان کا پل ہوں: میں کارکردگی کے میٹرکس کو ایسی حکمت عملیوں میں بدلتا ہوں جو میدان میں نمایاں فرق پیدا کرتی ہیں۔

  • Python
  • R
  • SQL
  • Power BI
  • Machine Learning
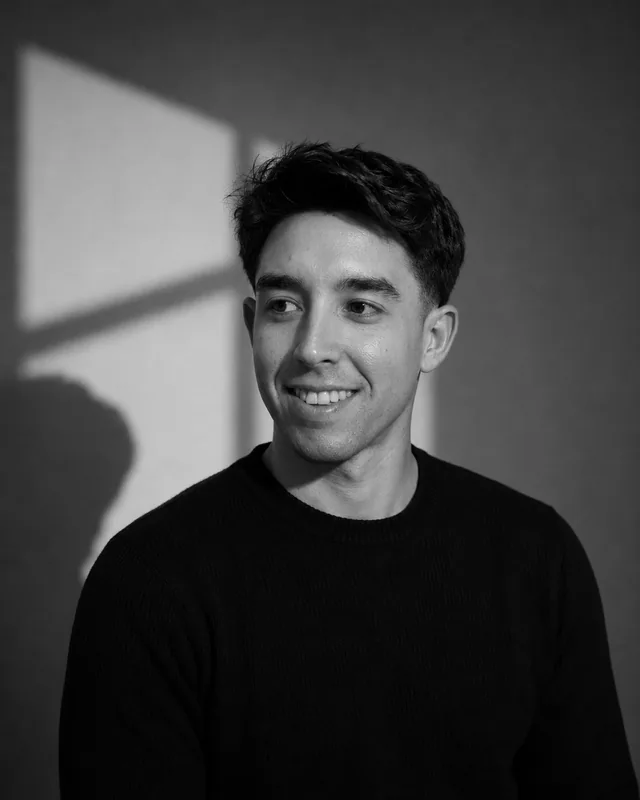
Retrato de Mario Álvarez

میرے بارے میں

ٹریک، سڑک اور مسابقتی تناظر کے ساتھ ڈیٹا

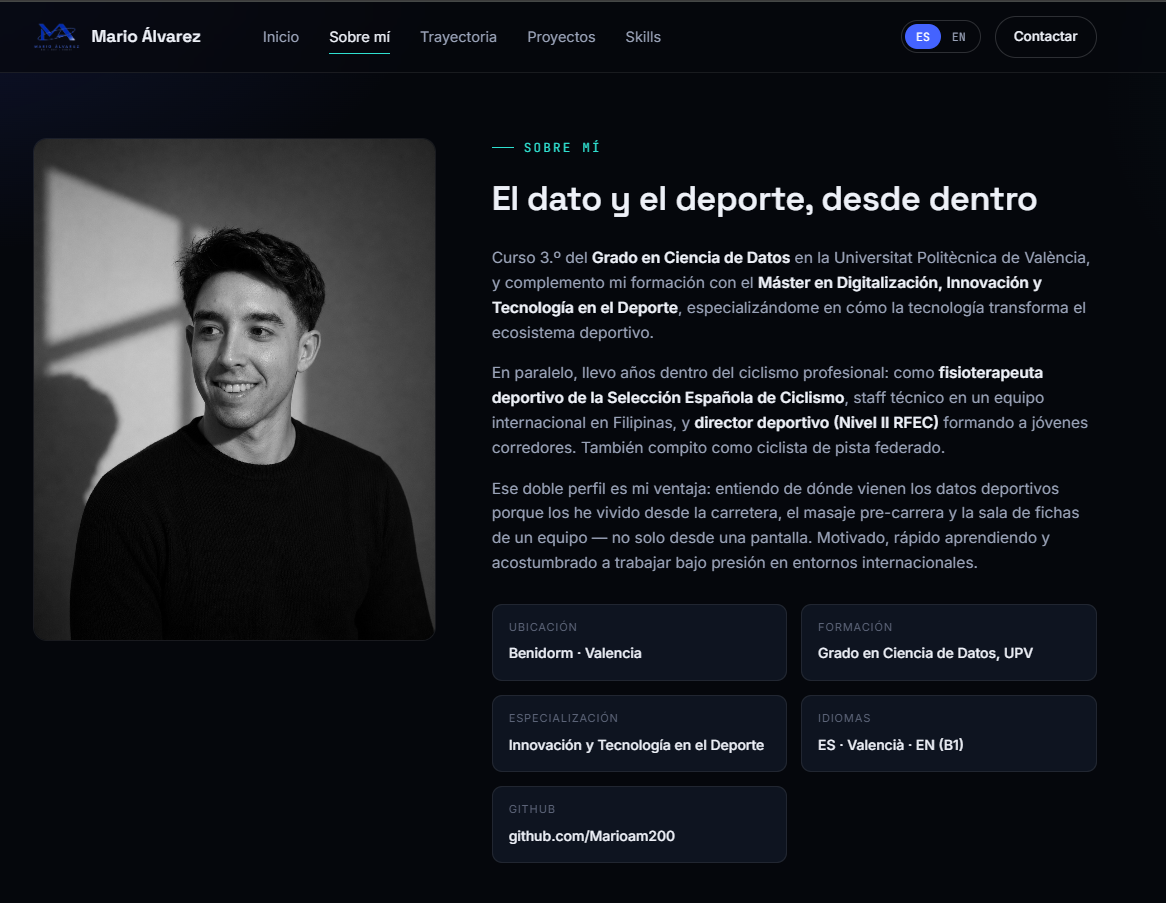
میں Mario Álvarez ہوں، UPV میں ڈیٹا سائنس کا طالب علم جو پروفیشنل سائیکلنگ کا حقیقی تجربہ رکھتا ہوں۔ میں ہر میٹرک کو ایسے فیصلے میں بدلنے کے لیے ڈیٹا کے تجزیے کو ایلیٹ کھیلوں کی کارکردگی کے ساتھ ملا دیتا ہوں جو نتائج کو بہتر بناتا ہے۔

مزید دیکھیں

UPV

تعلیم

ڈیٹا سائنس میں ڈگری، Universitat Politècnica de València۔

ایلیٹ

تجربہ

پروفیشنل سائیکلنگ ٹیم کے اندر حقیقی کام۔

Data + Sport

نقطہ نظر

کھیلوں کی کارکردگی کو بہتر بنانے کے لیے تجزیات کا اطلاق۔

تجربہ

دو دنیایں، ایک ہی زبان: کارکردگی

میں نے اعلیٰ ترین سطح پر مقابلہ کیا ہے اور آج میں ڈیٹا پر بھی وہی معیار لاگو کرتا ہوں: میں سمجھتا ہوں کہ ایک کھلاڑی کے لیے نمبر کا کیا مطلب ہے کیونکہ میں خود وہ کھلاڑی رہا ہوں۔

مزید دیکھیں

کام

پrogییکٹس

GitHub پر میرے پبلک ریپوزٹوریز کا خودکار انتخاب۔

تخصصات

  • HTML
  • Power BI
  • Python
  • R
  • SQL

VIS

HTML

This repository contains coursework, practical exercises, and study materials for a university data visualization course. It includes solved programming tasks using R and Python libraries like ggplot2 and Plotly, alongside practice dashboards built in Tableau.

GitHub پر دیکھیں
EVALUACION-DE-MODELOS-

HTML

This repository contains practical assignments for a university model evaluation course, covering topics such as cost-sensitive classification, fairness metrics on the COMPAS dataset, and model interpretability using partial dependence plots. The exercises and analyses are implemented using Python and R across Jupyter Notebooks and R Markdown reports.

GitHub پر دیکھیں

TRABAJO_MDP

An academic data analysis project in R that explores and characterizes a physicochemical crystal dataset. It covers data cleaning, preprocessing, and dimensionality reduction through Principal Component Analysis (PCA) using packages such as FactoMineR, factoextra, and ggplot2.

GitHub پر دیکھیں

TRABAJO_CORREDORES

Python

A Streamlit web application that helps manage cycling teams by scraping race and rider data from ProCyclingStats and FirstCycling to analyze upcoming events and cyclist specialties. It is built with Python using BeautifulSoup, Selenium, Pandas, and the Gemini API to process data and extract UCI points regulations from PDFs.

GitHub پر دیکھیں

COFIDIS

Python

Developed as an academic project, this tool scrapes UCI rankings and race data from ProCyclingStats to calculate race difficulty scores tailored to the Cofidis cycling team's calendar. It is built with Python, using Selenium and BeautifulSoup for web scraping, Pandas for data processing, and Streamlit for the interactive interface.

GitHub پر دیکھیں
تمام پروجیکٹس دیکھیں

کیا ہم ڈیٹا کے بارے میں بات کریں؟

مجھے اپنے پروجیکٹ کے بارے میں بتائیں اور ہم مل کر تلاش کرتے ہیں کہ وہ فیصلے کہاں ہیں جو کارکردگی کو بہتر بناتے ہیں۔

رابطے پر جائیں