นักวิทยาศาสตร์ข้อมูล · การวิเคราะห์กีฬา · วาเลนเซีย

ฉันเปลี่ยนข้อมูลให้เป็น การตัดสินใจที่ชัดเจน

ฉันคือสะพานเชื่อมระหว่างการวิเคราะห์ข้อมูลและกีฬาระดับสูง โดยแปลงตัวชี้วัดประสิทธิภาพเป็นกลยุทธ์ที่สร้างความแตกต่างในสนาม

  • Python
  • R
  • SQL
  • Power BI
  • Machine Learning
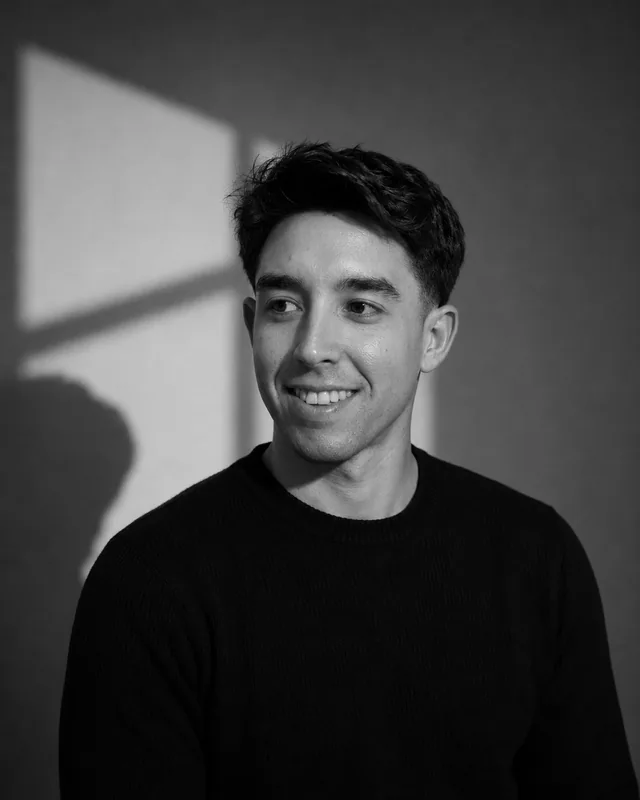
Retrato de Mario Álvarez

เกี่ยวกับฉัน

ข้อมูลในบริบทของสนาม ถนน และการแข่งขัน

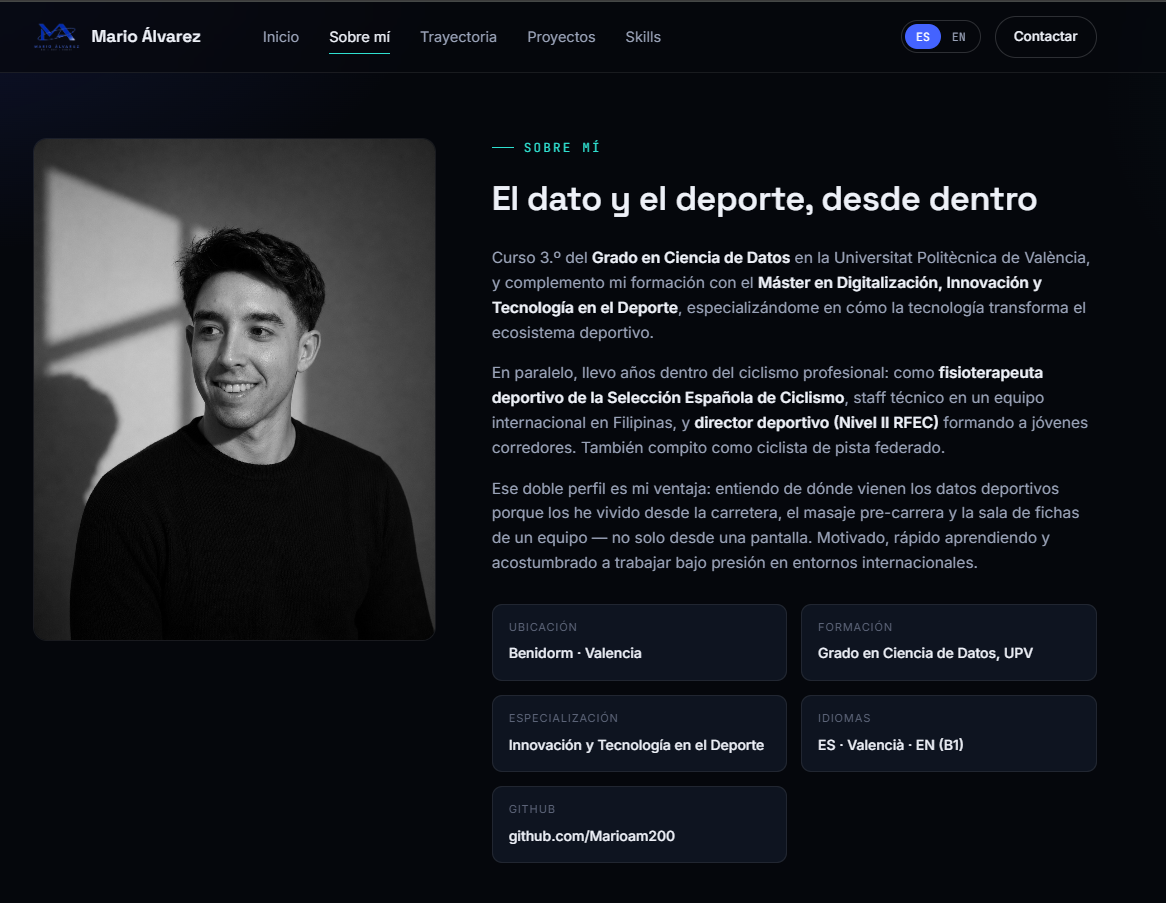
ฉันคือ Mario Álvarez นักศึกษา Data Science ที่ UPV พร้อมด้วยประสบการณ์จริงในวงการจักรยานอาชีพ ฉันผสมผสานการวิเคราะห์ข้อมูลเข้ากับประสิทธิภาพการกีฬาระดับสูง เพื่อเปลี่ยนทุกตัวชี้วัดให้เป็นการตัดสินใจที่ช่วยพัฒนาผลลัพธ์

ดูเพิ่มเติม

UPV

การศึกษา

ปริญญาตรีสาขาวิทยาศาสตร์ข้อมูล Universitat Politècnica de València

ระดับสูง

ประสบการณ์

การทำงานจริงภายในทีมจักรยานอาชีพ

Data + Sport

แนวทาง

การวิเคราะห์ที่ประยุกต์ใช้เพื่อการพัฒนาประสิทธิภาพการกีฬา

ประสบการณ์

สองโลก ภาษาเดียวกัน: ประสิทธิภาพ

ฉันเคยแข่งขันในระดับสูงสุดและในปัจจุบันนำเกณฑ์เดียวกันนั้นมาใช้กับข้อมูล: ฉันเข้าใจความหมายของตัวเลขที่มีต่อนักกีฬาเพราะฉันเคยเป็นนักกีฬานั้นมาก่อน

ดูเพิ่มเติม

งาน

โครงงาน

การเลือกคลังเก็บข้อมูลสาธารณะของฉันบน GitHub โดยอัตโนมัติ

ความเชี่ยวชาญพิเศษ

  • HTML
  • Power BI
  • Python
  • R
  • SQL

VIS

HTML

This repository contains coursework, practical exercises, and study materials for a university data visualization course. It includes solved programming tasks using R and Python libraries like ggplot2 and Plotly, alongside practice dashboards built in Tableau.

ดูบน GitHub
EVALUACION-DE-MODELOS-

HTML

This repository contains practical assignments for a university model evaluation course, covering topics such as cost-sensitive classification, fairness metrics on the COMPAS dataset, and model interpretability using partial dependence plots. The exercises and analyses are implemented using Python and R across Jupyter Notebooks and R Markdown reports.

ดูบน GitHub

TRABAJO_MDP

An academic data analysis project in R that explores and characterizes a physicochemical crystal dataset. It covers data cleaning, preprocessing, and dimensionality reduction through Principal Component Analysis (PCA) using packages such as FactoMineR, factoextra, and ggplot2.

ดูบน GitHub

TRABAJO_CORREDORES

Python

A Streamlit web application that helps manage cycling teams by scraping race and rider data from ProCyclingStats and FirstCycling to analyze upcoming events and cyclist specialties. It is built with Python using BeautifulSoup, Selenium, Pandas, and the Gemini API to process data and extract UCI points regulations from PDFs.

ดูบน GitHub

COFIDIS

Python

Developed as an academic project, this tool scrapes UCI rankings and race data from ProCyclingStats to calculate race difficulty scores tailored to the Cofidis cycling team's calendar. It is built with Python, using Selenium and BeautifulSoup for web scraping, Pandas for data processing, and Streamlit for the interactive interface.

ดูบน GitHub
ดูโปรเจกต์ทั้งหมด

มาคุยเรื่องข้อมูลกันไหม?

เล่าโปรเจกต์ของคุณให้ฉันฟัง แล้วเรามาหาด้วยกันว่าการตัดสินใจที่จะช่วยพัฒนาประสิทธิภาพซ่อนอยู่ตรงไหน

ไปที่หน้าติดต่อ